The Watchdog Needs a Watchdog: How a Rescue Script Hung Inside Itself
· 4 min read
After colliding with network ghosts on our self-hosted runners, we learned one rule: networks and virtual machines are extremely unreliable entities.
To avoid running to the server every time the pipeline “stuck fast,” we wrote a Supervisor script (to manage the process) and a completely independent Watchdog script. Its logic was primitive and reliable: if the Supervisor doesn’t respond, kill it, send us a nice Telegram alert, and restart the process.
This was a perfect, self-healing system. Or so we thought.
First Blood: Telegram’s Betrayal
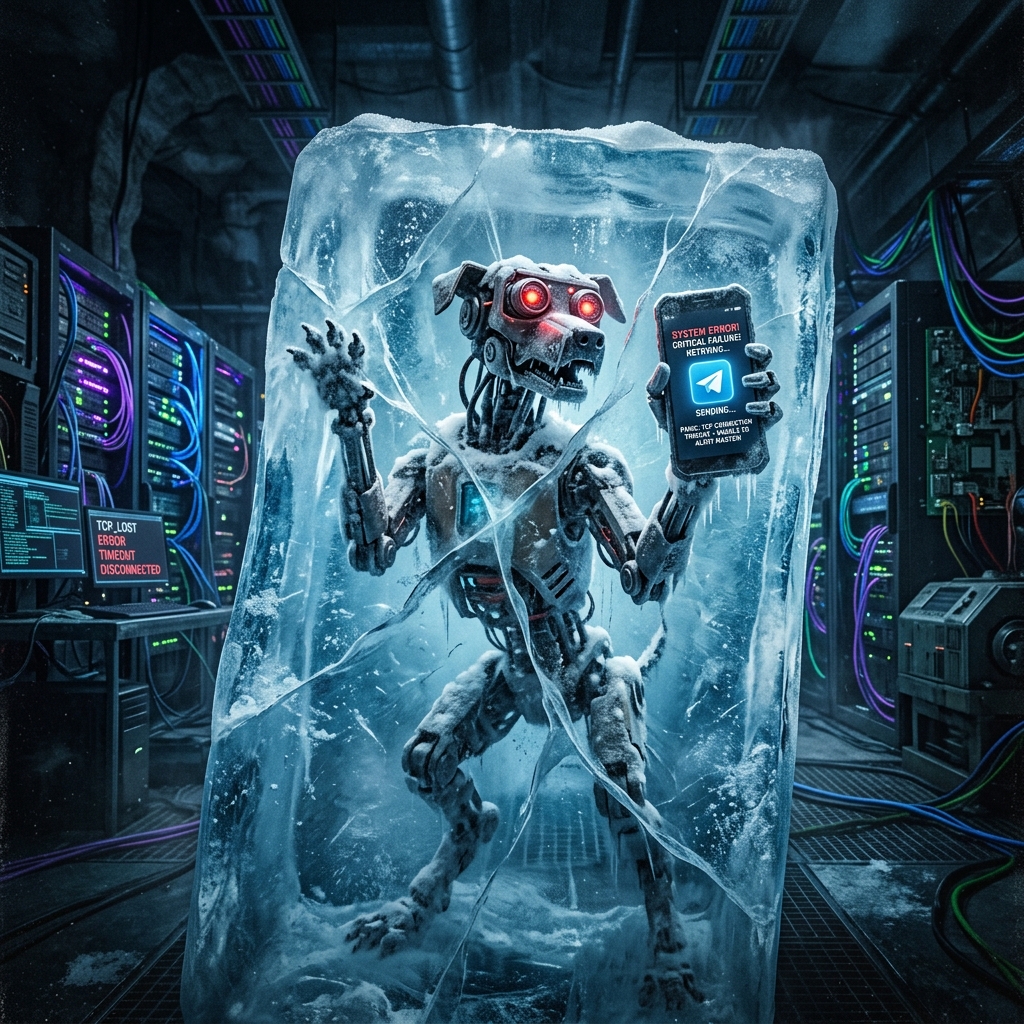
One day, the Watchdog correctly caught a Supervisor hang and initiated the rescue procedure. As a first step, it attempted to execute the Alert() function to send us a Telegram message via standard Invoke-RestMethod.
And then the system froze forever.
It turned out that after the host woke from sleep mode, the TCP connection to the Telegram API had “frozen” at the operating system level. At the same time, the built-in PowerShell timeout was completely ignored by the underlying platform.
The Watchdog hung dead trying to send a message about a hang, never reaching the life-saving restart function.
We learned our first lesson: never block recovery with a network call. We moved the alert dispatch into an isolated background process (Start-Job) with a brutal 20-second timeout. If the network was silent—we simply dropped the alert and proceeded to recovery.
Trench Warfare
We thought that after the Telegram patch, we were safe. But the infrastructure began striking from all sides. Over the following weeks, we methodically closed new holes, taking hit after hit:
- The Supervisor crashed, leaving behind a locked system mutex, preventing its own restart. We had to write logic to intercept abandoned mutexes.
- The GitHub API periodically lagged, and the script lost its retry logic. We had to patch the state machine.
- The virtual machine started throwing new, previously unseen connection drop signatures (
VERR_TIMEOUT). We populated our crash dictionaries.
We surrounded the code with so many checks and try/catch layers that the script looked bulletproof. The system was supposed to silently and efficiently heal itself under any circumstances.
Deep Windows Coma (The Final Boss)
Two more weeks passed. The system worked stably, until the CI suddenly stuck fast again.
We logged into the server and opened the Watchdog logs. The last entry read: "Hang confirmation 1/2". After this line in the logs, there was a yawning void 14 hours long.
There were no exceptions, no script crashes, no records of killed processes in the operating system’s Event Logs. An absolute freeze.
We started disassembling the Watchdog code line by line. Right after the log entry came the only call without our own custom timeout: a local system query Get-CimInstance Win32_Process. With this query, the Watchdog was asking Windows itself: “Is the Supervisor process alive?”.
The truth turned out to be terrifying. Due to a failure deep in the bowels of the OS, the WMI (Windows Management Instrumentation) service had also gone into a coma. The Watchdog asked the system a question, and the operating system simply never answered it, freezing the rescue script forever. The very tool we used to check for hangs had hung itself.
Conclusion: Recursive Paranoia
The Watchdog needed its own timer even for trivial built-in OS commands. We had to wrap the basic local Get-CimInstance call in the same strict background process with a timeout as the network requests.
This became our main lesson in self-hosted infrastructure: you cannot trust anything. Not the network, not someone else’s API, not the built-in timeouts of the programming language, not even the local system APIs of your own OS. If you write code that must save a system from hanging, every single line of it must have external, paranoid time control. Quis custodiet ipsos custodes? (Who will watch the watchmen?).
But infrastructure calls are only half the problems of a complex project. Sometimes the programming language itself starts hiding basic things from us. How the classic size_t type managed to escape our C++ parser on Linux three times, breaking Continuous Integration—read about it in the next episode.